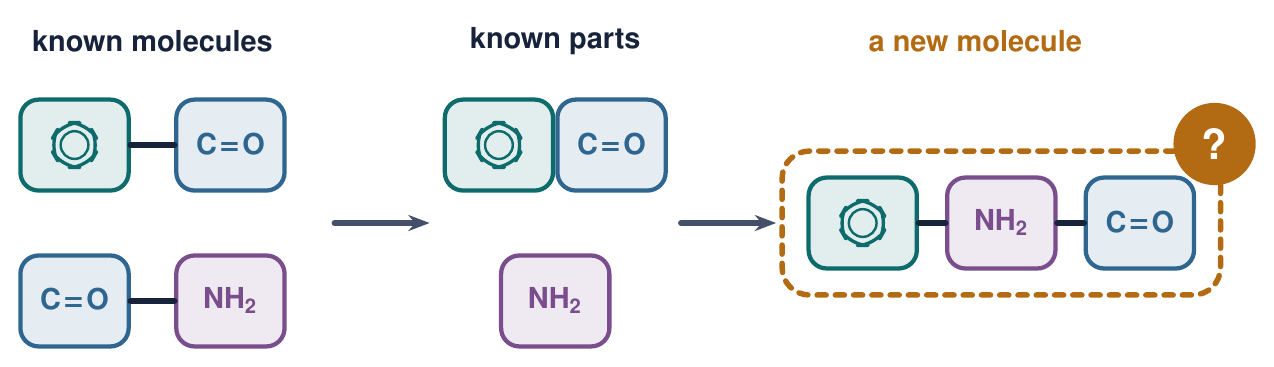
Knowing the parts, missing the whole: does machine learning understand new molecules built from what it already knows?
Knowing the parts, missing the whole
Overview
- Introduction: how machine learning learns, and how chemists and computers read molecules
- Motivation: where the data runs out, and what counts as new
- GMD: the benchmark: familiar parts, new molecules
- Results: where today’s models break
- Takeaways
So how does a computer learn anything at all?
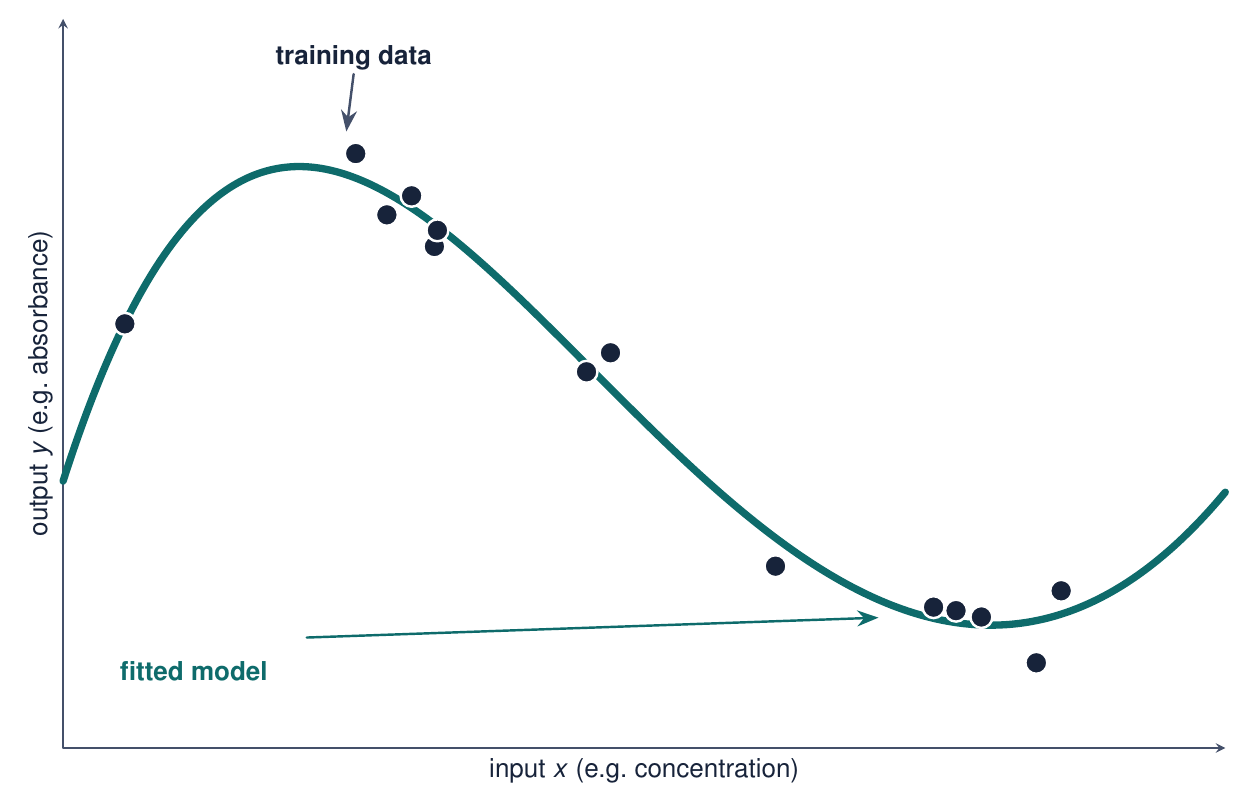
Teaching a computer from examples
- We give the computer examples: inputs and the correct answers
- It tunes a flexible formula until its predictions match those answers
- “Learning” just means finding the parameters with the smallest error
You already do this: fit a curve to two or three experimental points, then predict other amounts of reactant without running more experiments.
Can we trust that curve everywhere, even far from the points we measured?
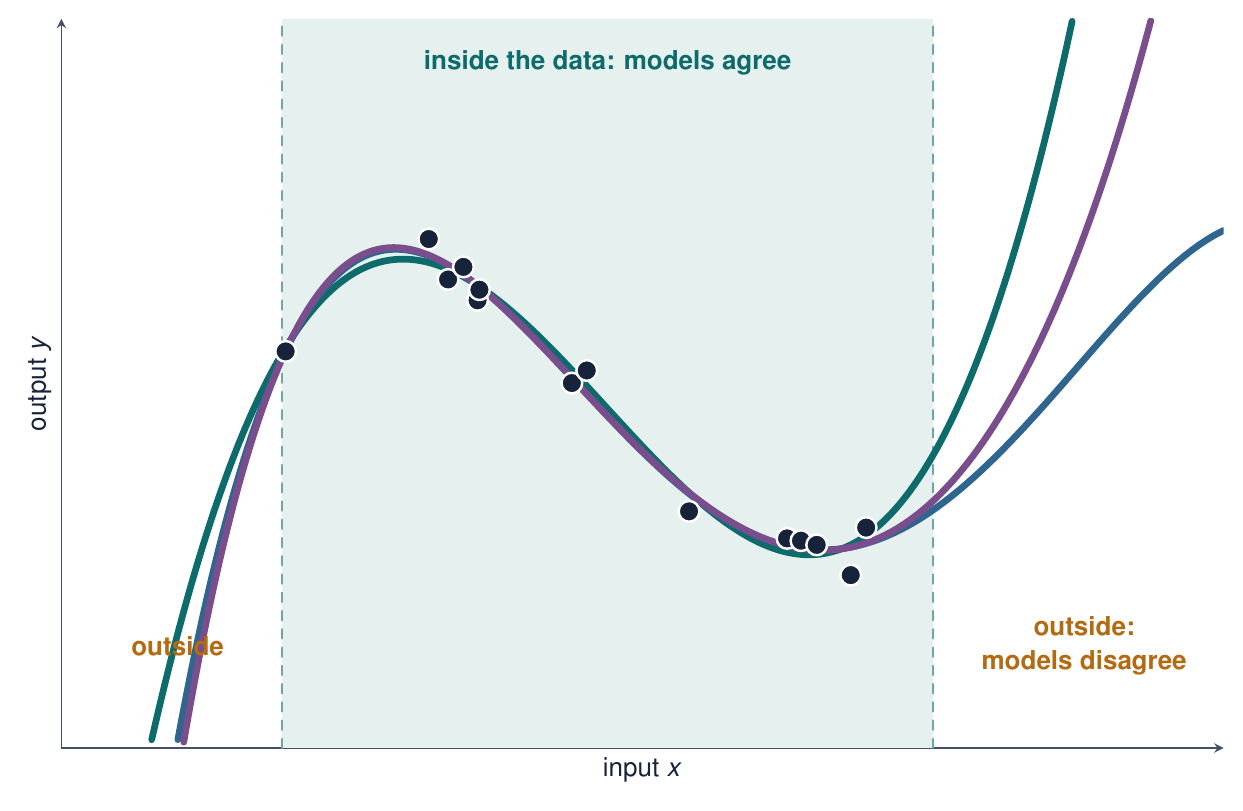
Inside the data versus outside it
- Between known points the model interpolates, and is usually reliable
- Beyond them it extrapolates, and nothing in the training checks it
- A very flexible model can pass every training point and still go wild just outside
A small error on the training data says little about data the model has never seen.
Let’s see how different our interpretation of a molecule is from a computer’s.
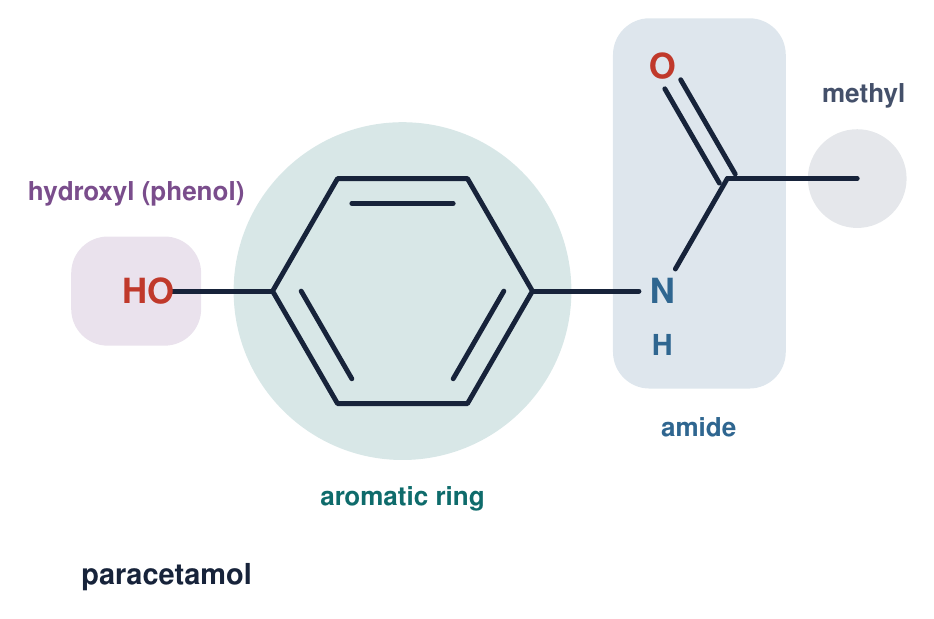
How a chemist reads a molecule
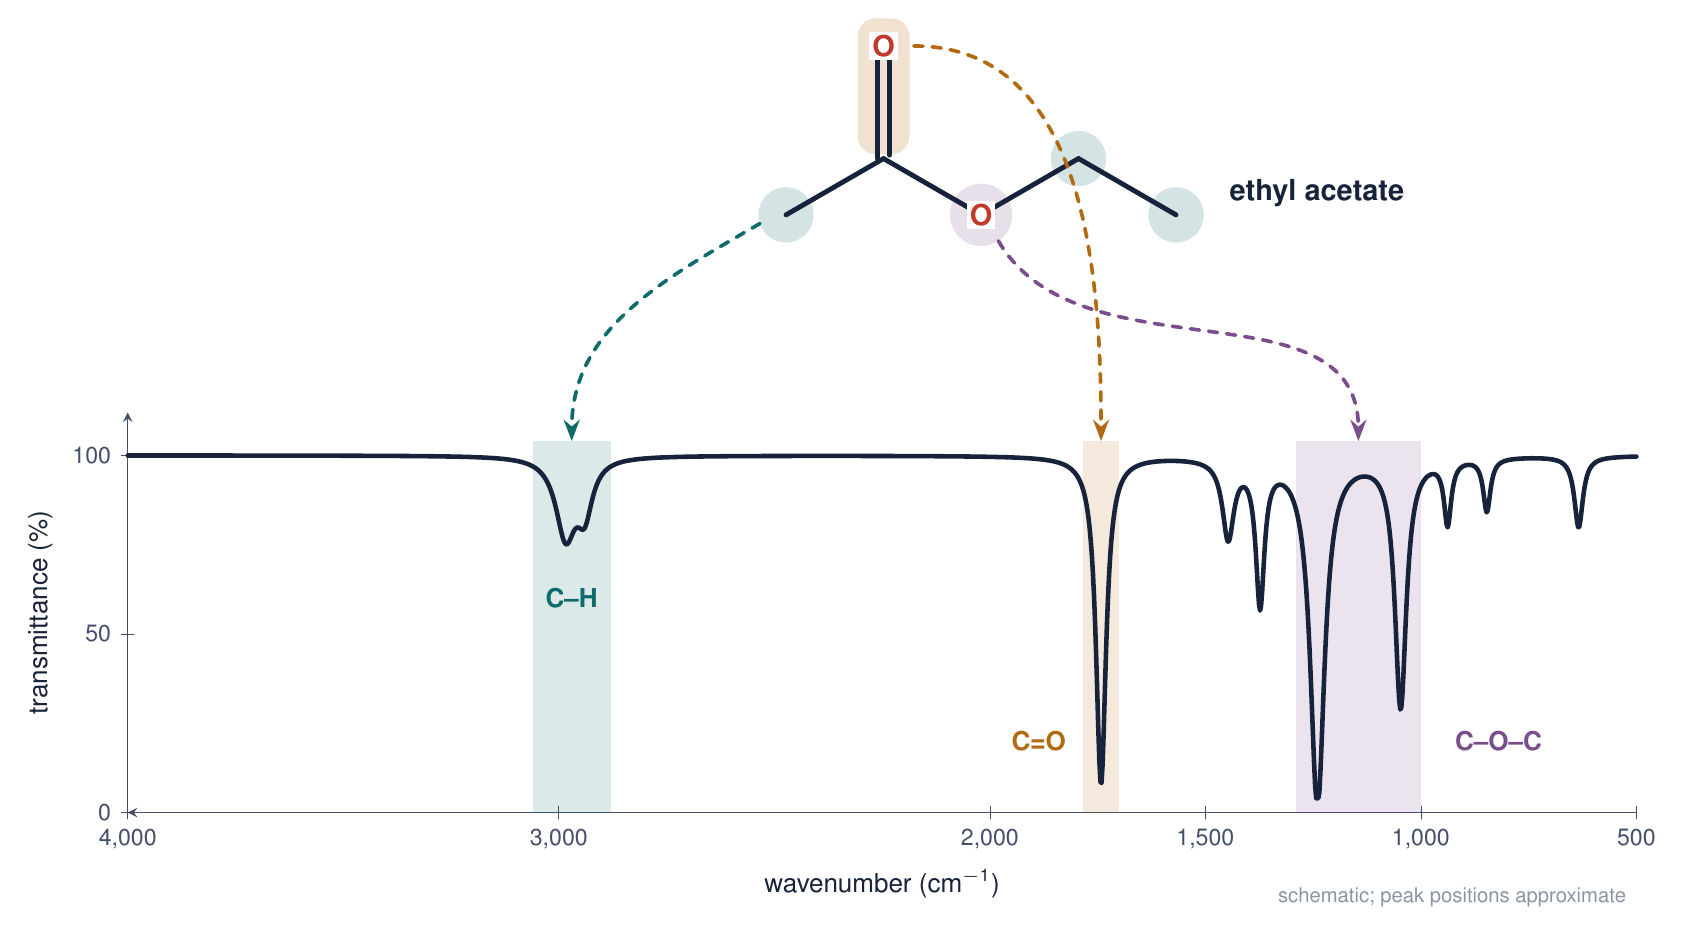
How is that different from how a computer reads a molecule?
What does a molecule look like to a computer?
- Input: each atom’s element and 3D position, exactly what an
.xyzfile holds - Output: the energy E, and the force on every atom
- There are many ways to give a molecule to a computer: 3D coordinates, adjacency matrices, molecular graphs, SMILES strings, fingerprints
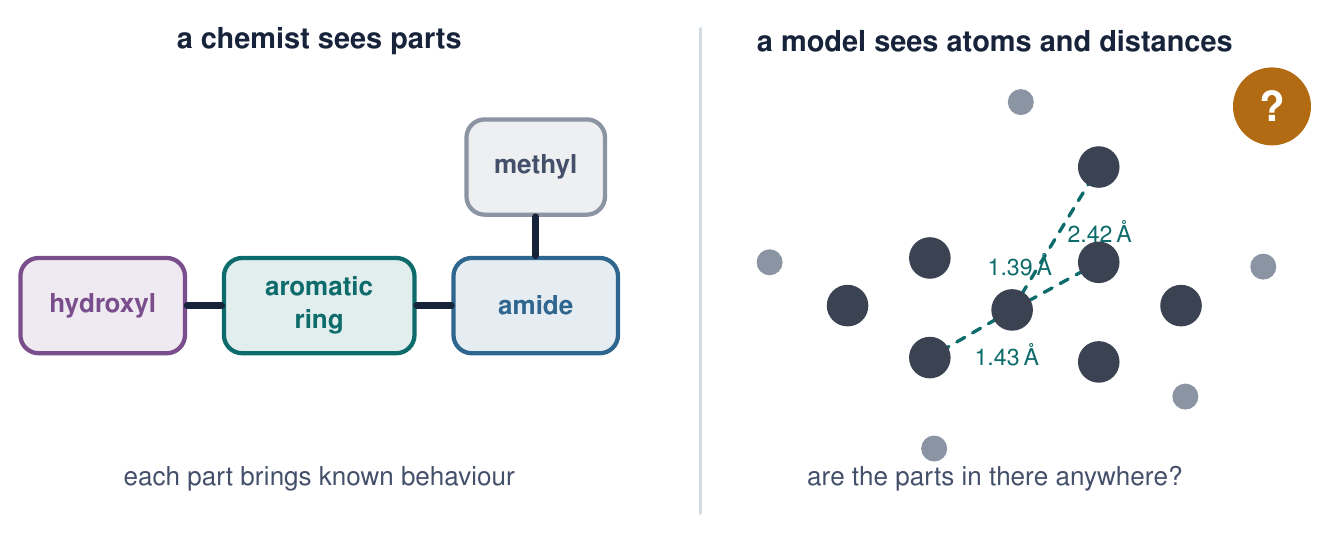
The model never sees a label like “carbonyl” or “ring”: only elements and distances.
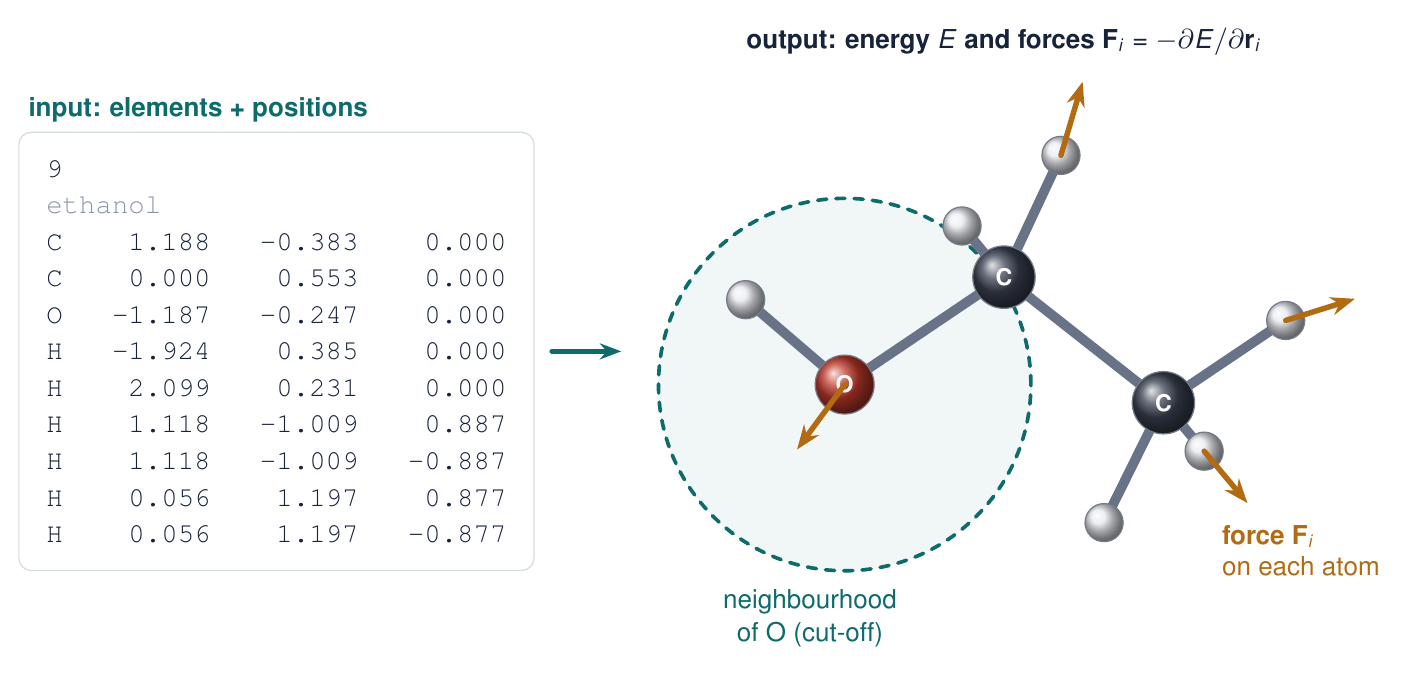
Then does machine learning read molecules the way a chemist does?
Does machine learning read molecules this way?
- The model learns from whole molecules, one geometry at a time
- Nothing forces it to learn “parts” the way a chemist does
- It might learn rules, or it might memorise the molecules it was shown
If every part of a new molecule is familiar, does the model find the whole familiar?
Where to get these data, and how?
Any method can supply the data and become a teacher
- From CCSD(T) to GFN2-xTB, every method gives energies and forces for a geometry
- So any of them can supply training data
- Datasets range from ten small molecules (MD17) to over 100 million calculations (OMol25)
A model is at best as accurate as the method that produced its data.
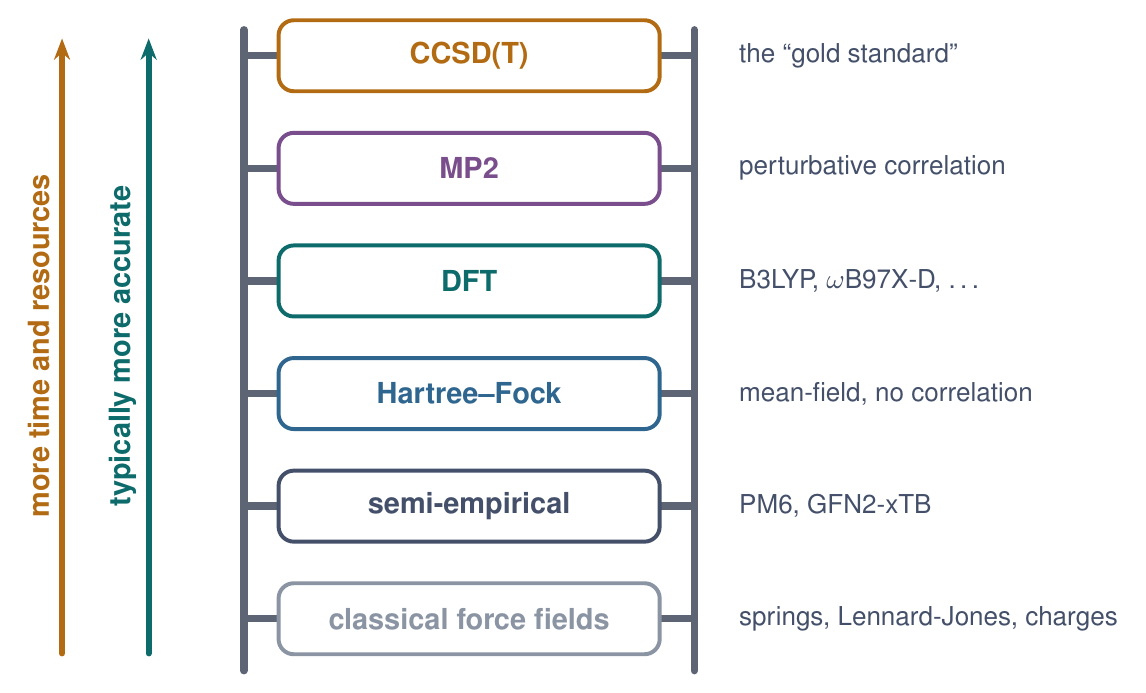
If these methods already give us energies and forces, why not just keep using them?
Why we invented semi-empirical methods
- Cost grows steeply with size: roughly N⁴ for Hartree–Fock, N⁵ for MP2, N⁷ for CCSD(T)
- Molecular dynamics needs energies and forces at millions of time steps
- Semi-empirical methods replaced expensive integrals with fitted parameters, trading some accuracy for speed
Every step down the ladder makes the same trade: accuracy for time and computer resources.
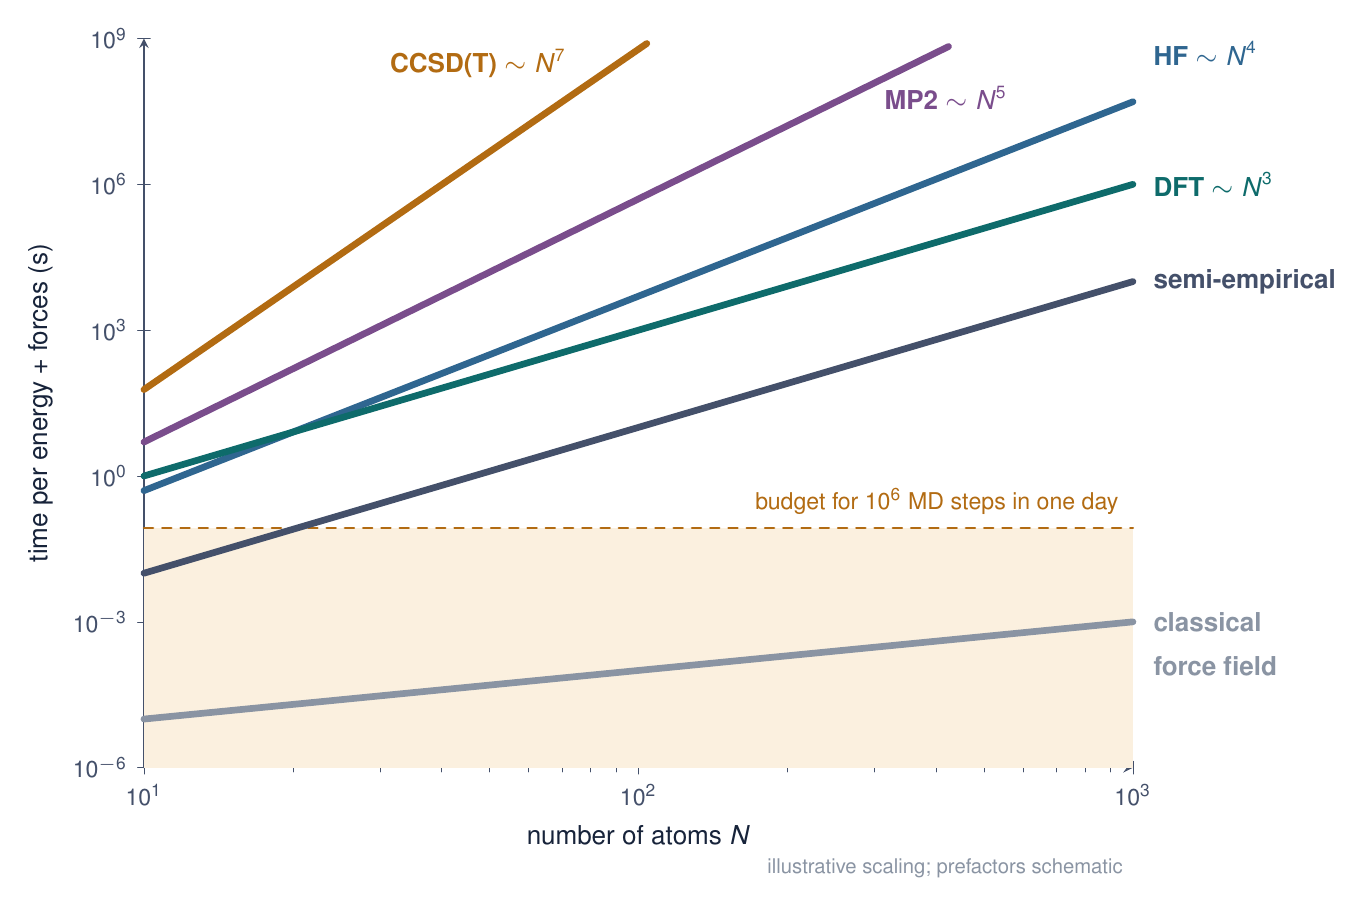
Machine learning makes a similar trade, by fitting to data. So what kind of method is it?
Enter machine-learning potentials
- Learn from reference calculations once
- Then predict energies and forces in milliseconds, close to the accuracy of the reference
- Nanosecond MD at near-reference accuracy becomes routine
Is machine learning a numerical, a semi-empirical, or an empirical method?
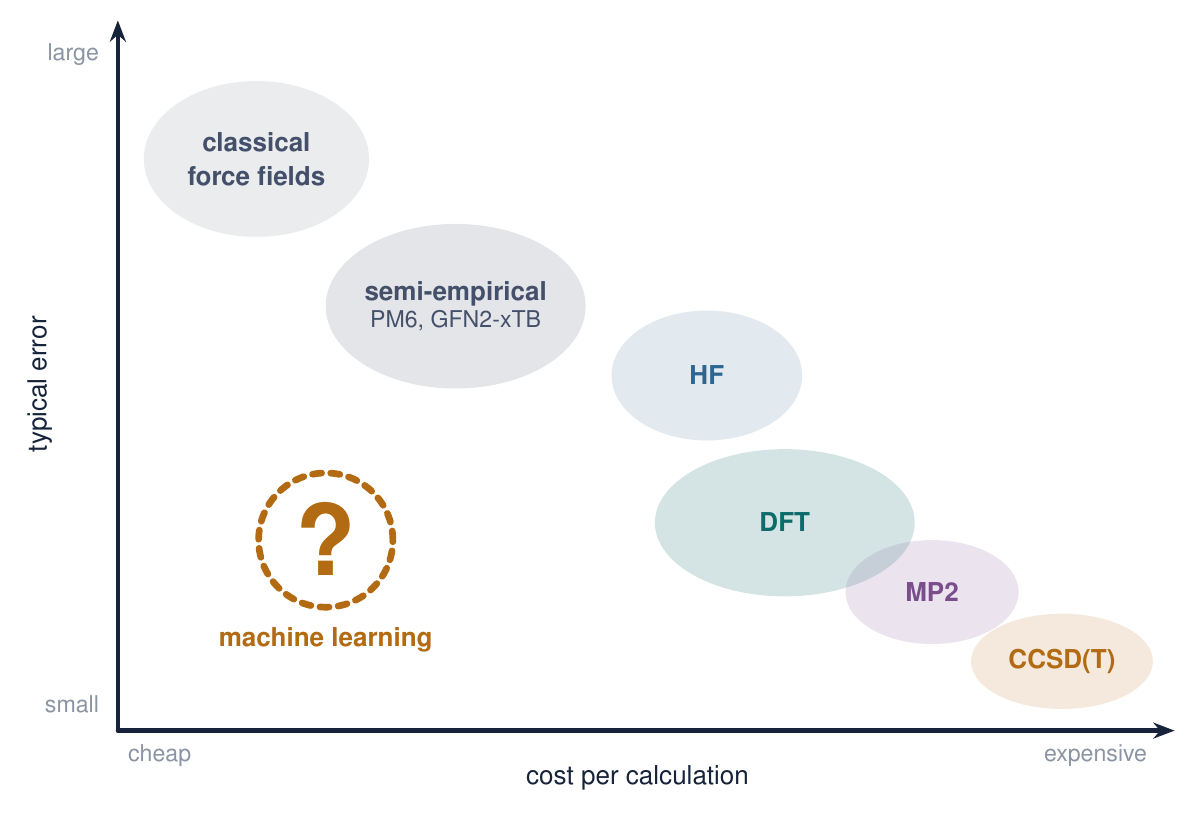
Whatever it is, it can learn from huge datasets. What if one model learned all of chemistry?
Universal models
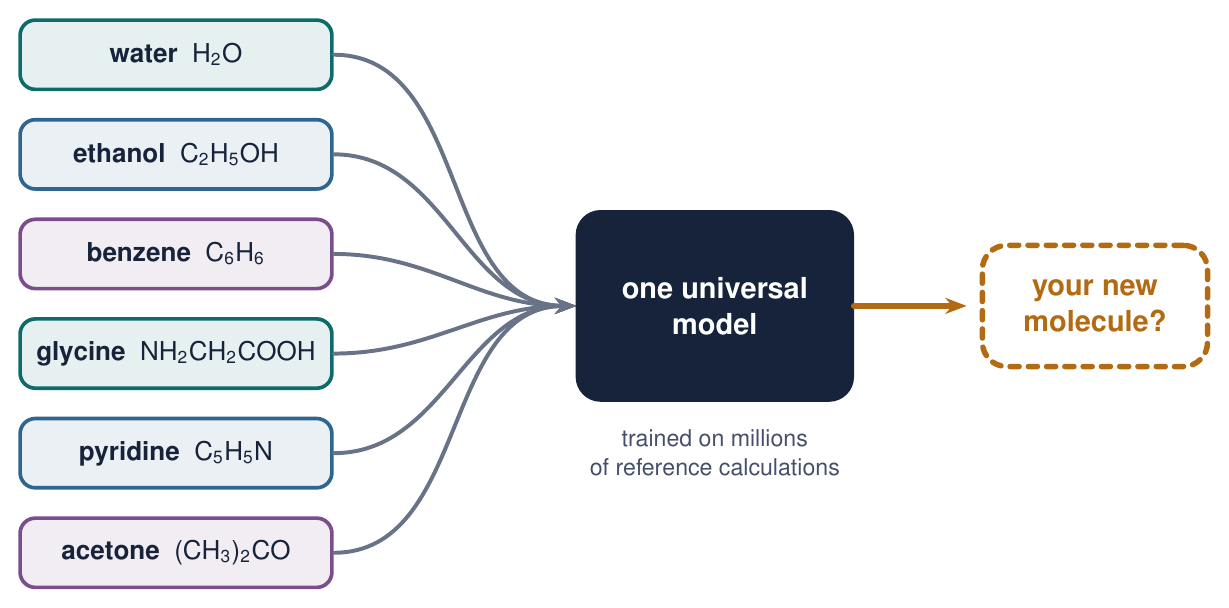
- Train once on millions of DFT calculations across chemistry
- One model for many molecules, with no new DFT for each system
- Examples: MACE-OFF, MACE-MP-0, PET-MAD, models trained on SPICE and OMol25
The promise: download a model and simulate your molecule. But what has the model actually learned about chemistry?
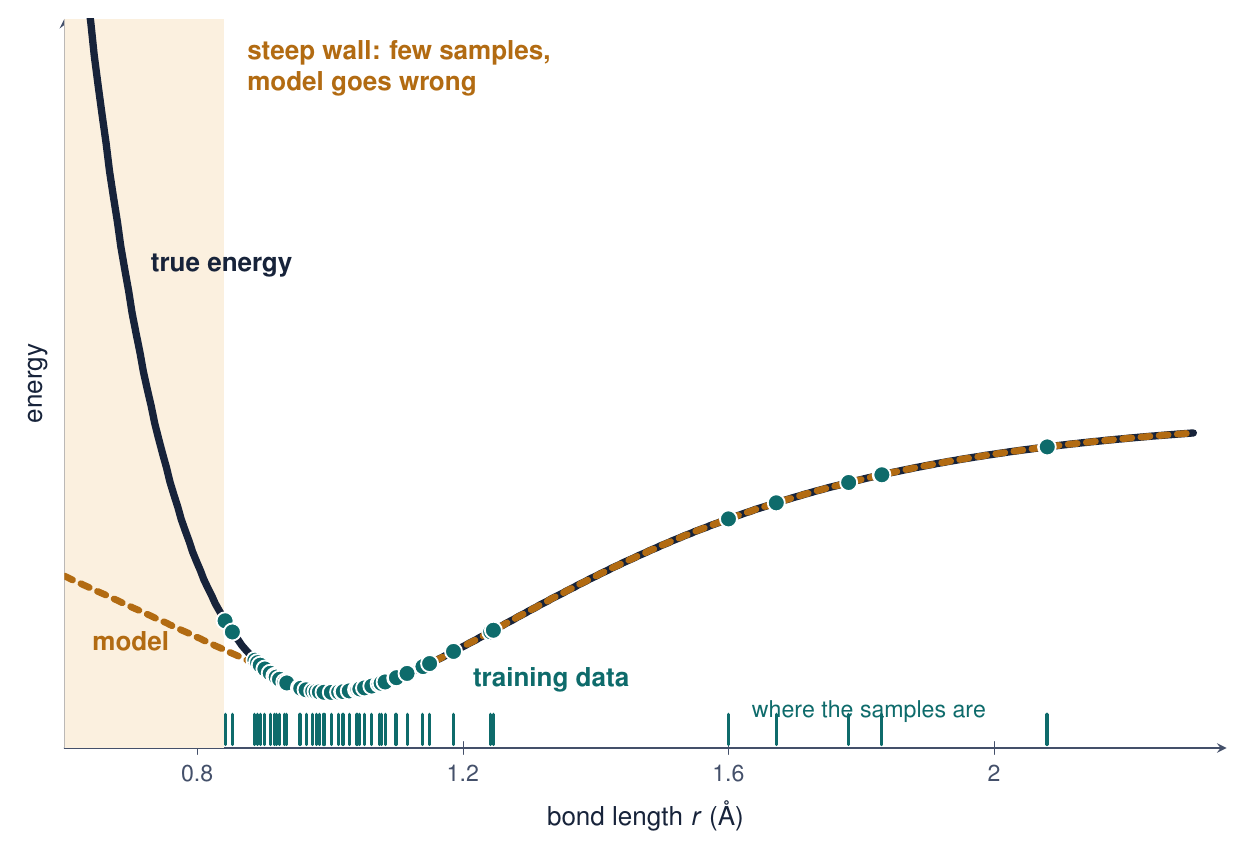
Even with millions of molecules, what happens where the data runs out?
What the data covers
- A model is only checked where its training data are
- MD at room temperature samples the energy well densely, and the steep repulsive wall almost never
- On the wall the model has to guess, and it guesses wrong
High-energy geometries the data does not cover: one kind of out-of-distribution.
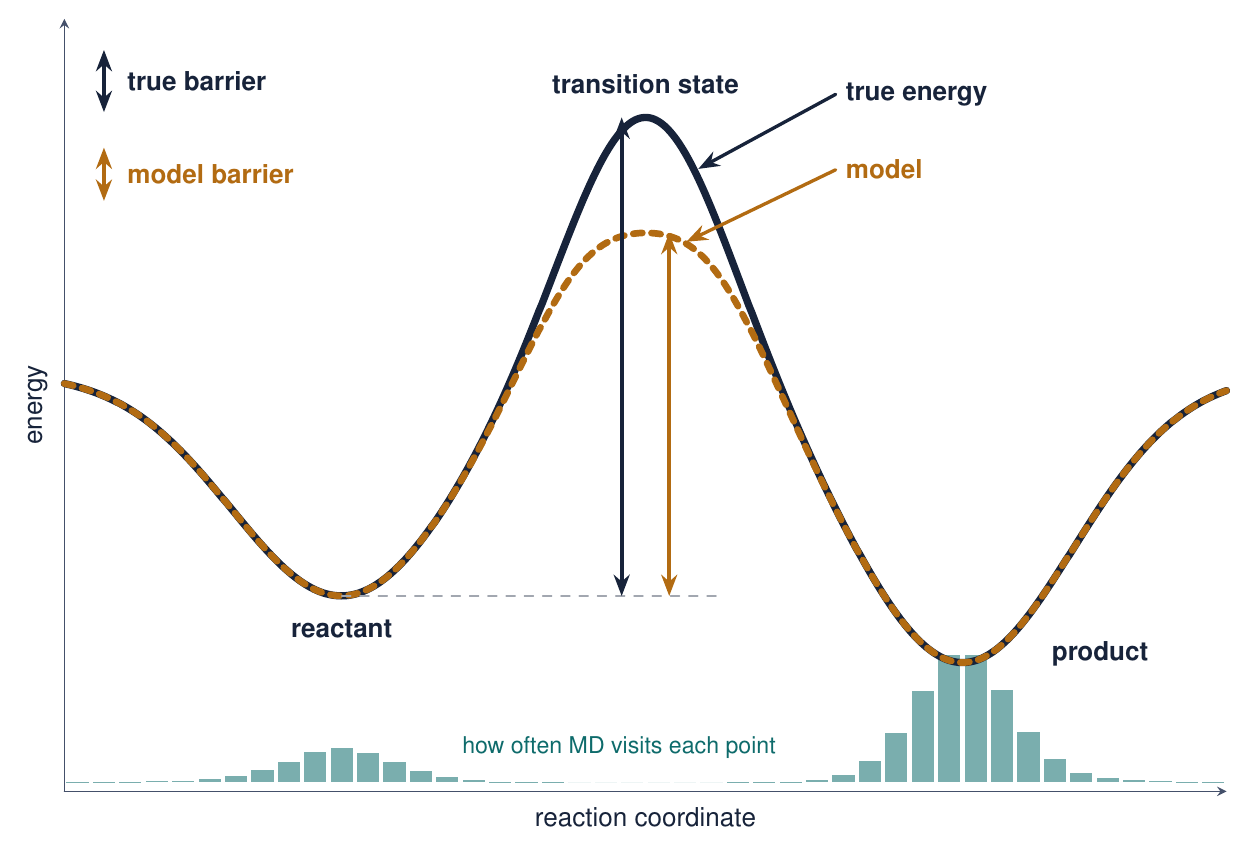
Now think of a reaction. Which point on the path does MD visit least?
Reactions: the rarest point matters most
- MD spends almost all its time in the reactant and product wells
- The transition state is visited rarely, so it is barely in the data
- At 298 K, every 1.4 kcal/mol of barrier error is a factor of 10 in the rate
Rare events the data barely covers: a second kind of out-of-distribution.
Steep walls, rare events… what else counts as out-of-distribution?
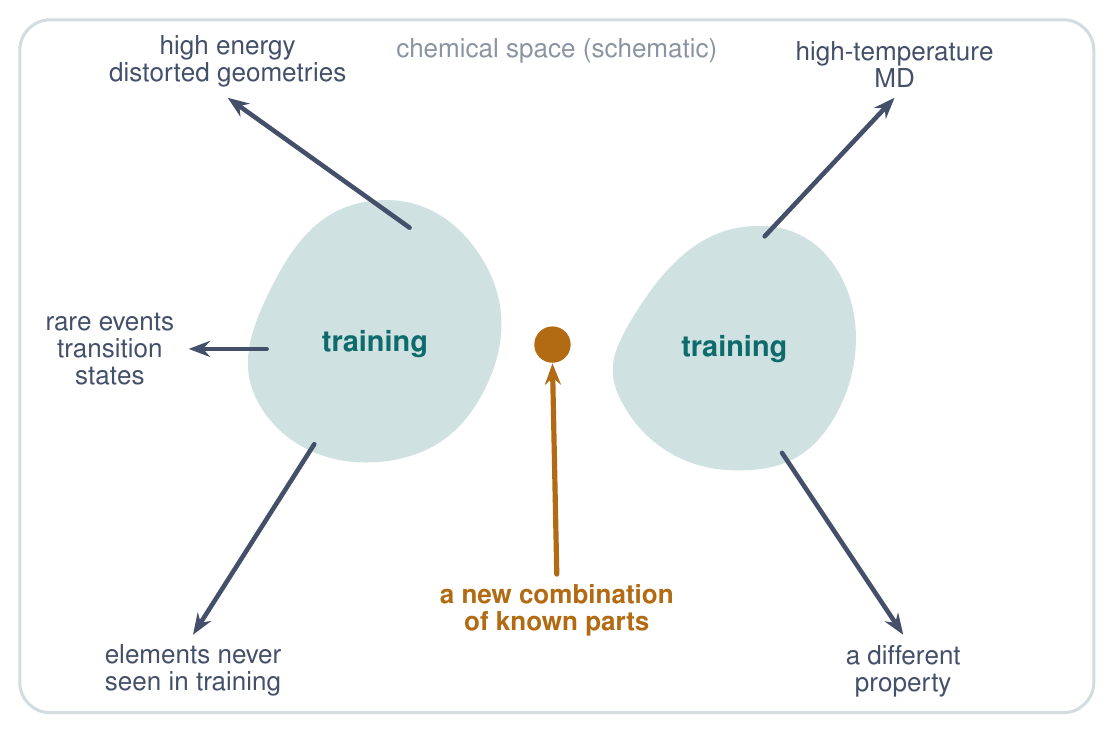
Many ways to be out-of-distribution
Out-of-distribution: anything the training data does not represent, where the model has to go beyond its data rather than fill in between it.
- High-energy geometries; rare events
- Higher temperature than in training
- Elements, charges or spin states never seen
- Solvent or surfaces, when trained in vacuum
- A new combination of known groups
That last one is the least tested. What would a test of it look like?
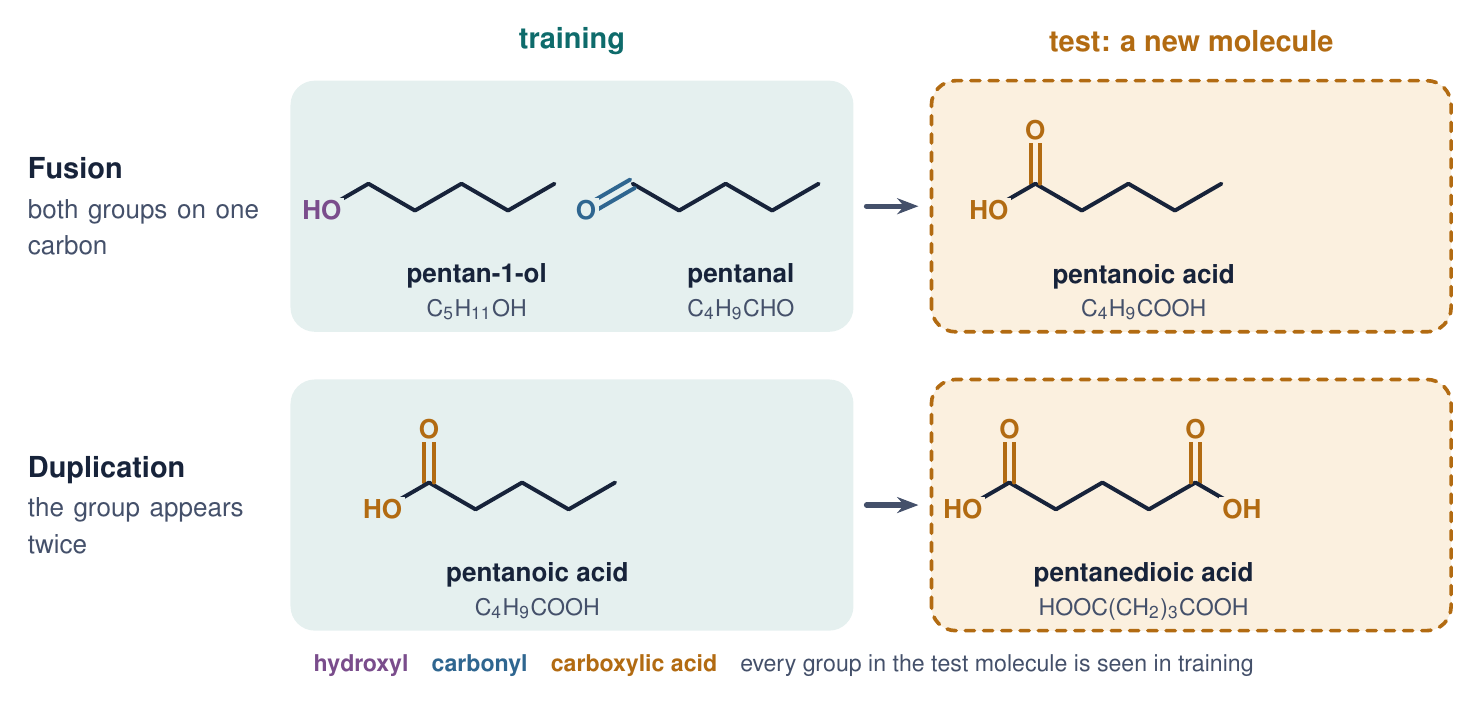
Our choice: scaffold out-of-distribution
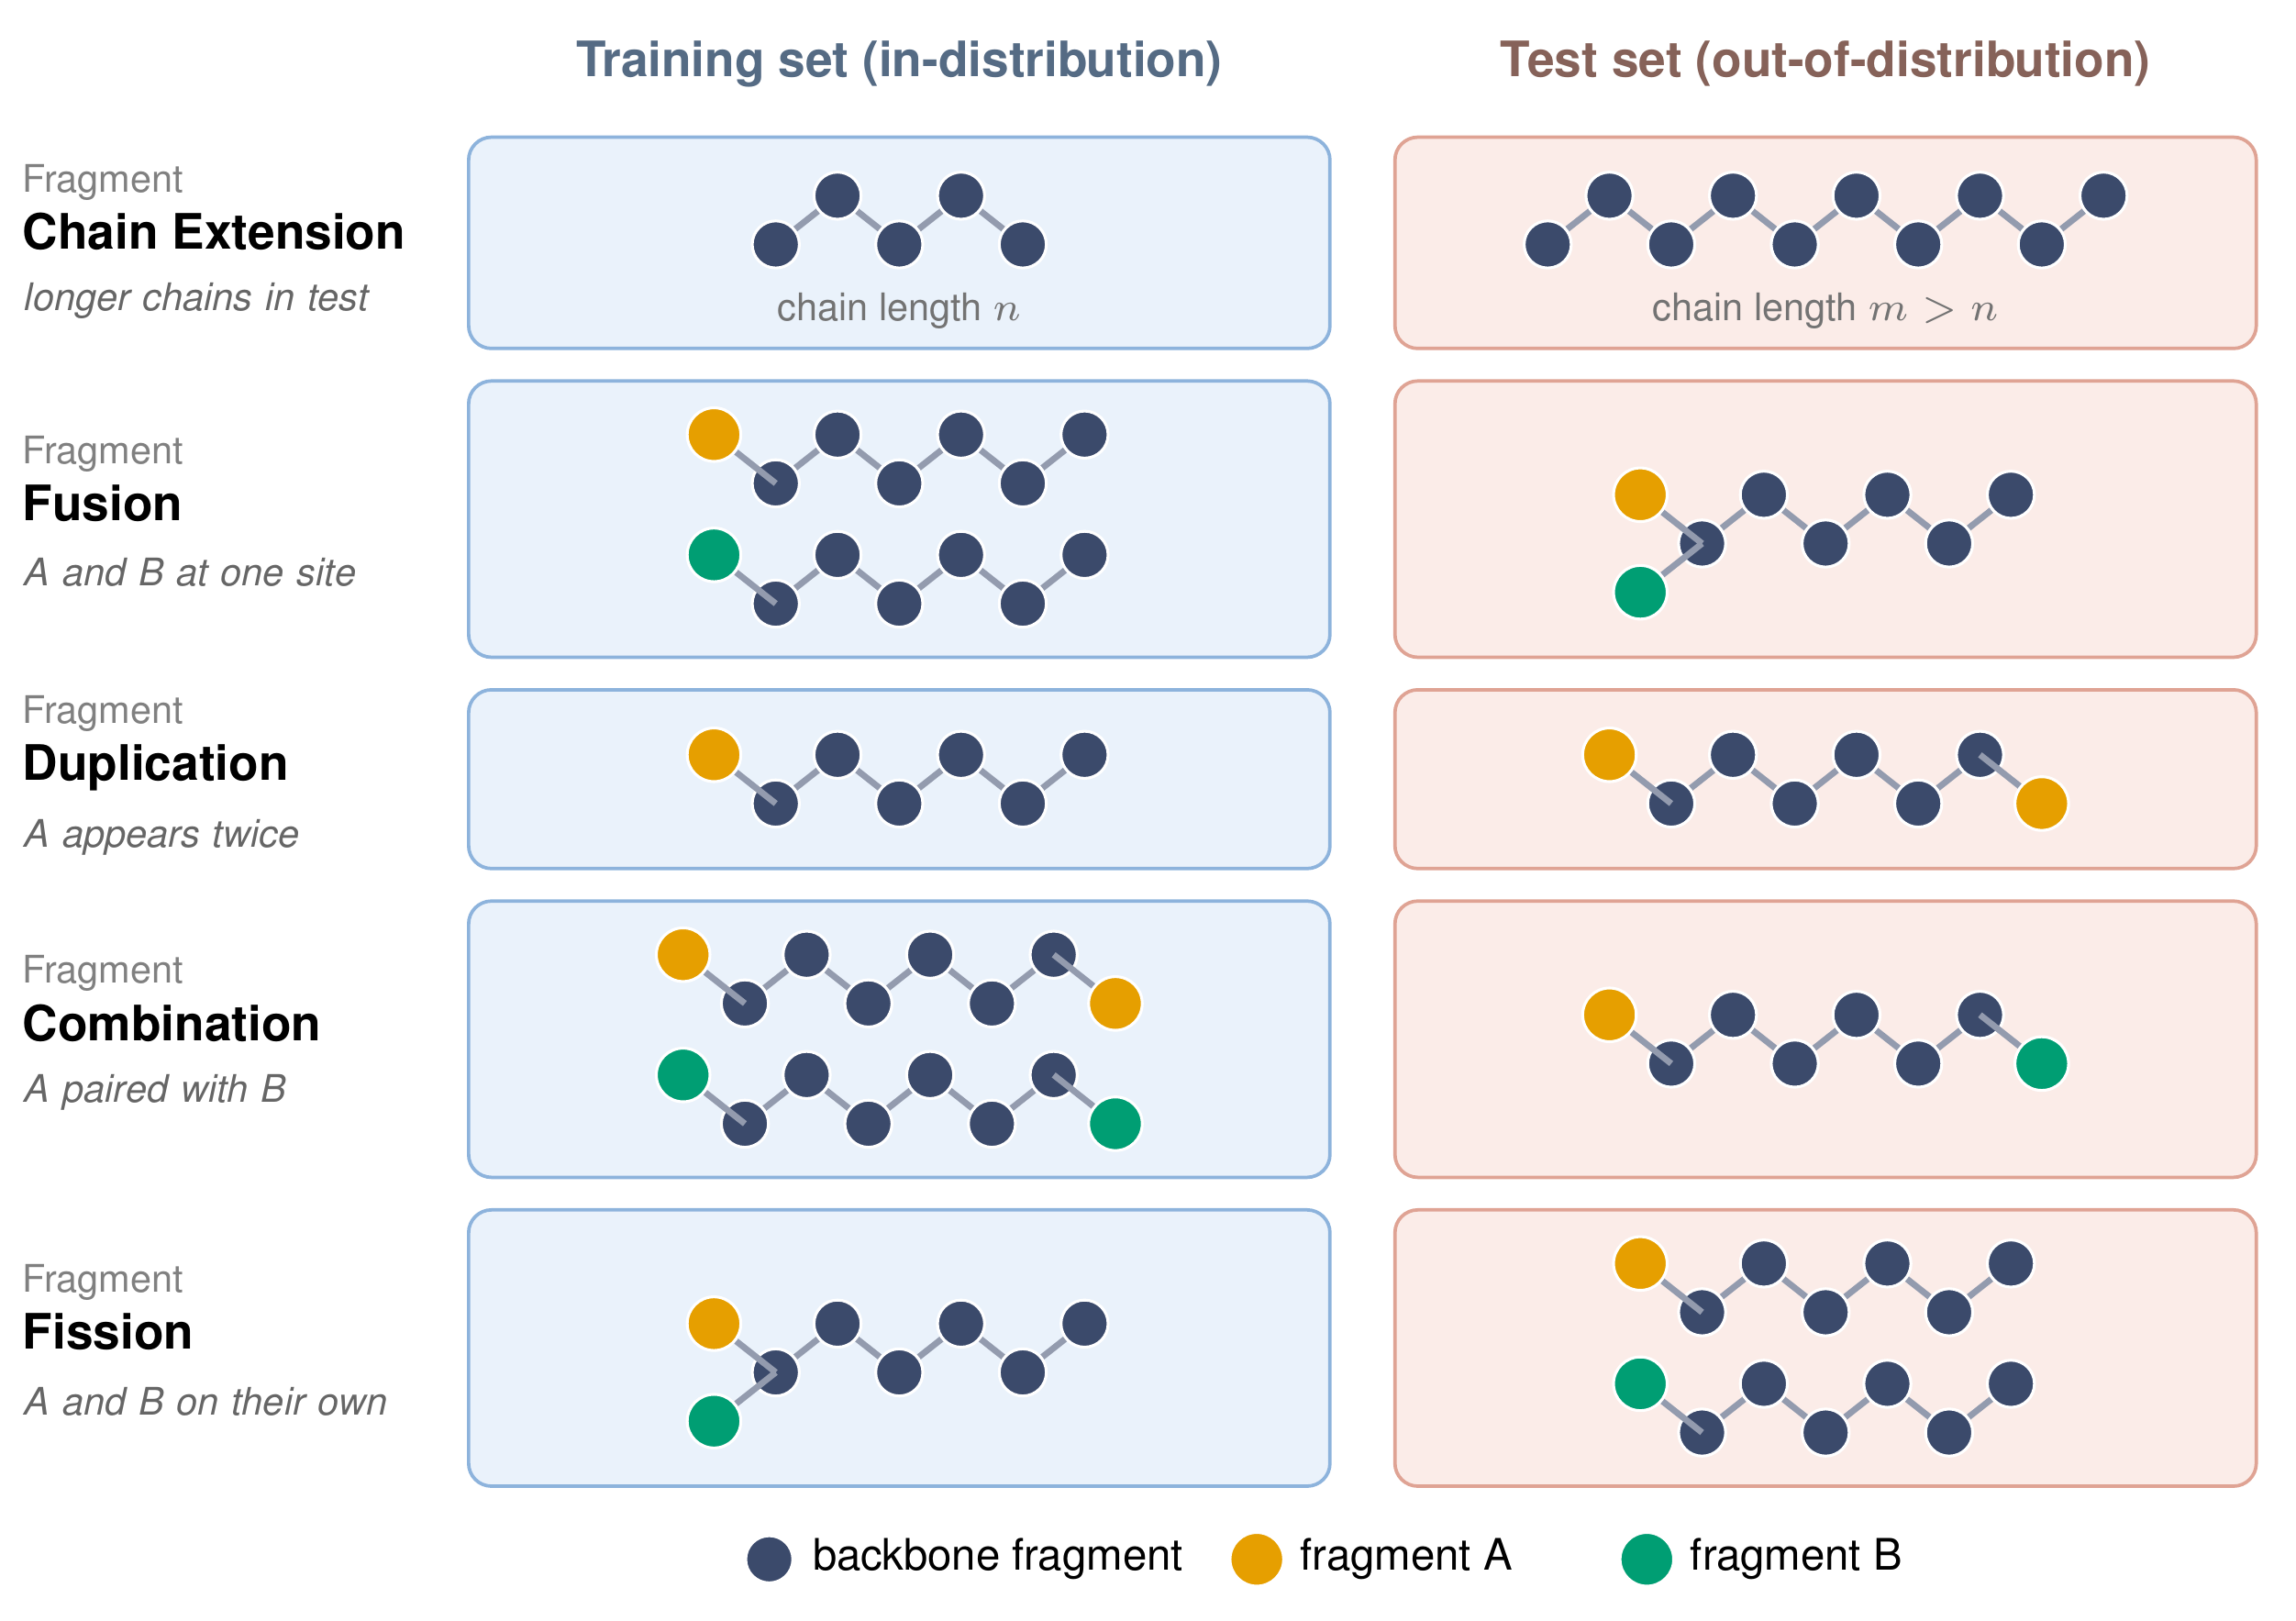
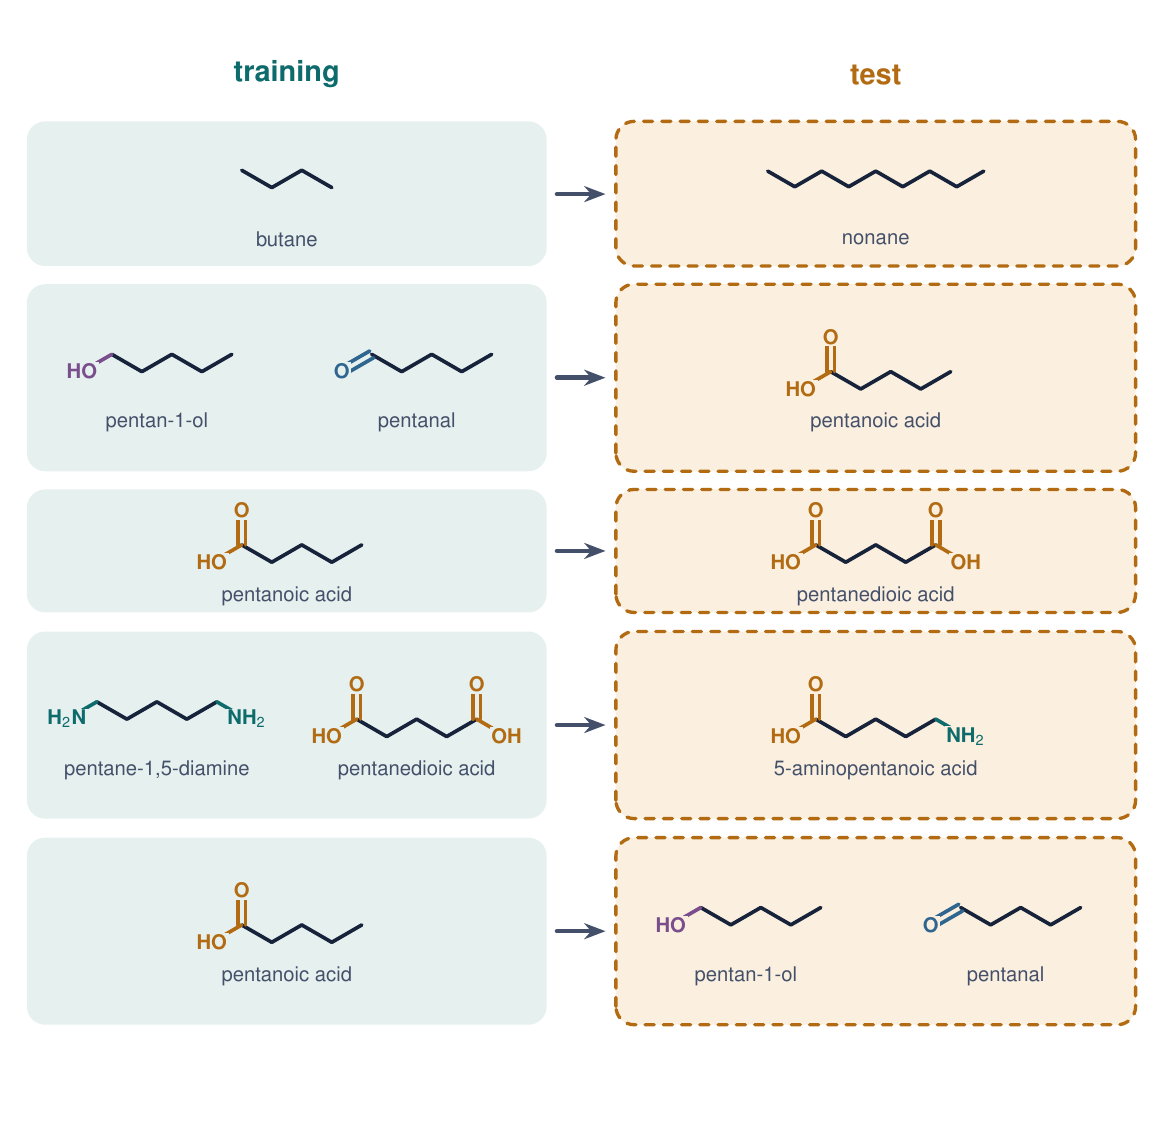
- Fusion: –OH and C=O seen apart; tested together on one carbon, as –COOH
- Duplication: one –COOH seen; tested with two
Every group is in training; only the molecule is new.
To run this test, we need a dataset built for it. That is GMD.
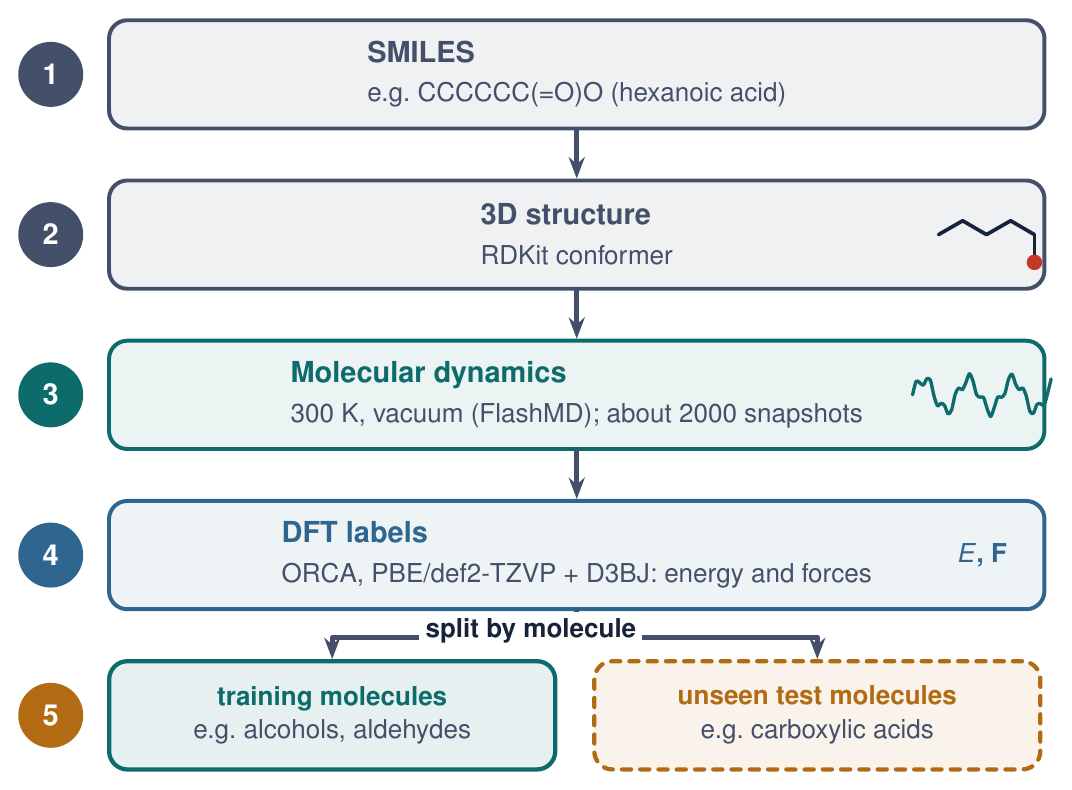
GMD: Generalisation for Molecular Dynamics
- Carbon chains carrying –OH, –CHO, –COOH or –NH2
- MD for each molecule, DFT energies and forces for every snapshot
- Training and test sets contain different molecules, not just different snapshots
Usually models are tested on new shapes of known molecules. GMD tests them on new molecules.
So which new molecules do we test them on?
Five ways to build a new molecule from known parts
So how do today’s models do?
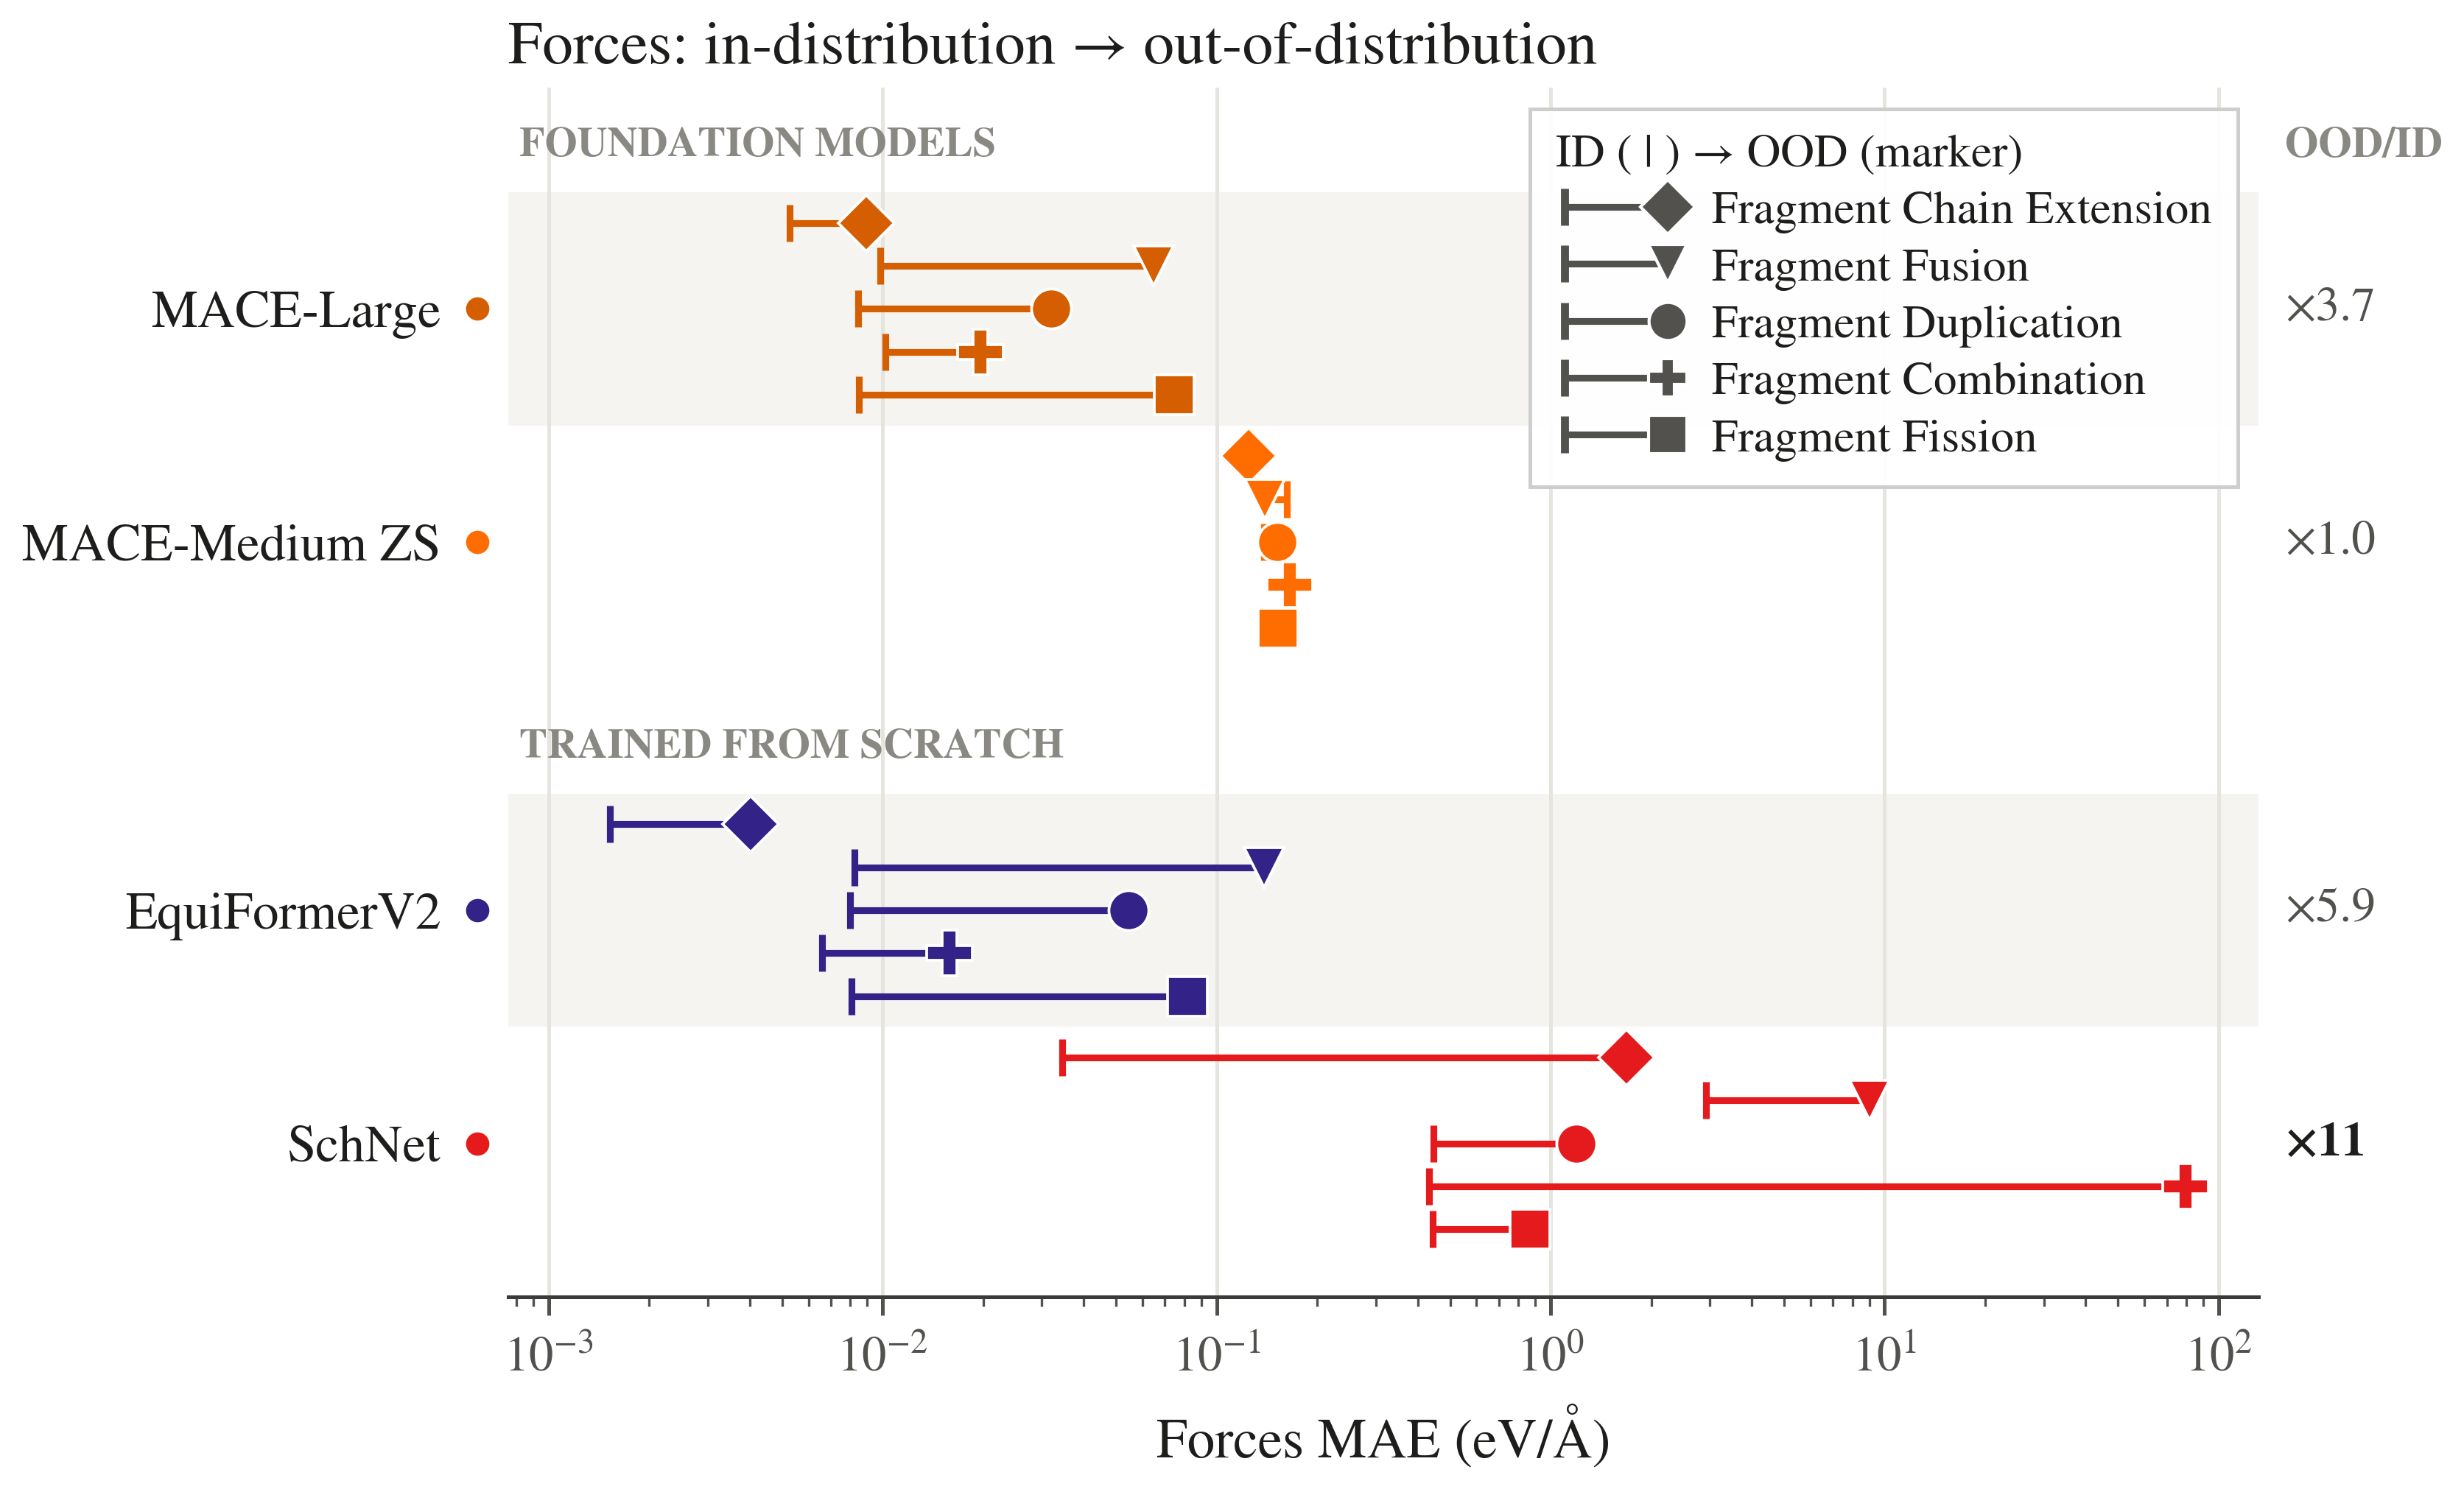
Known molecules versus new molecules
But where inside the molecule do these errors actually appear?
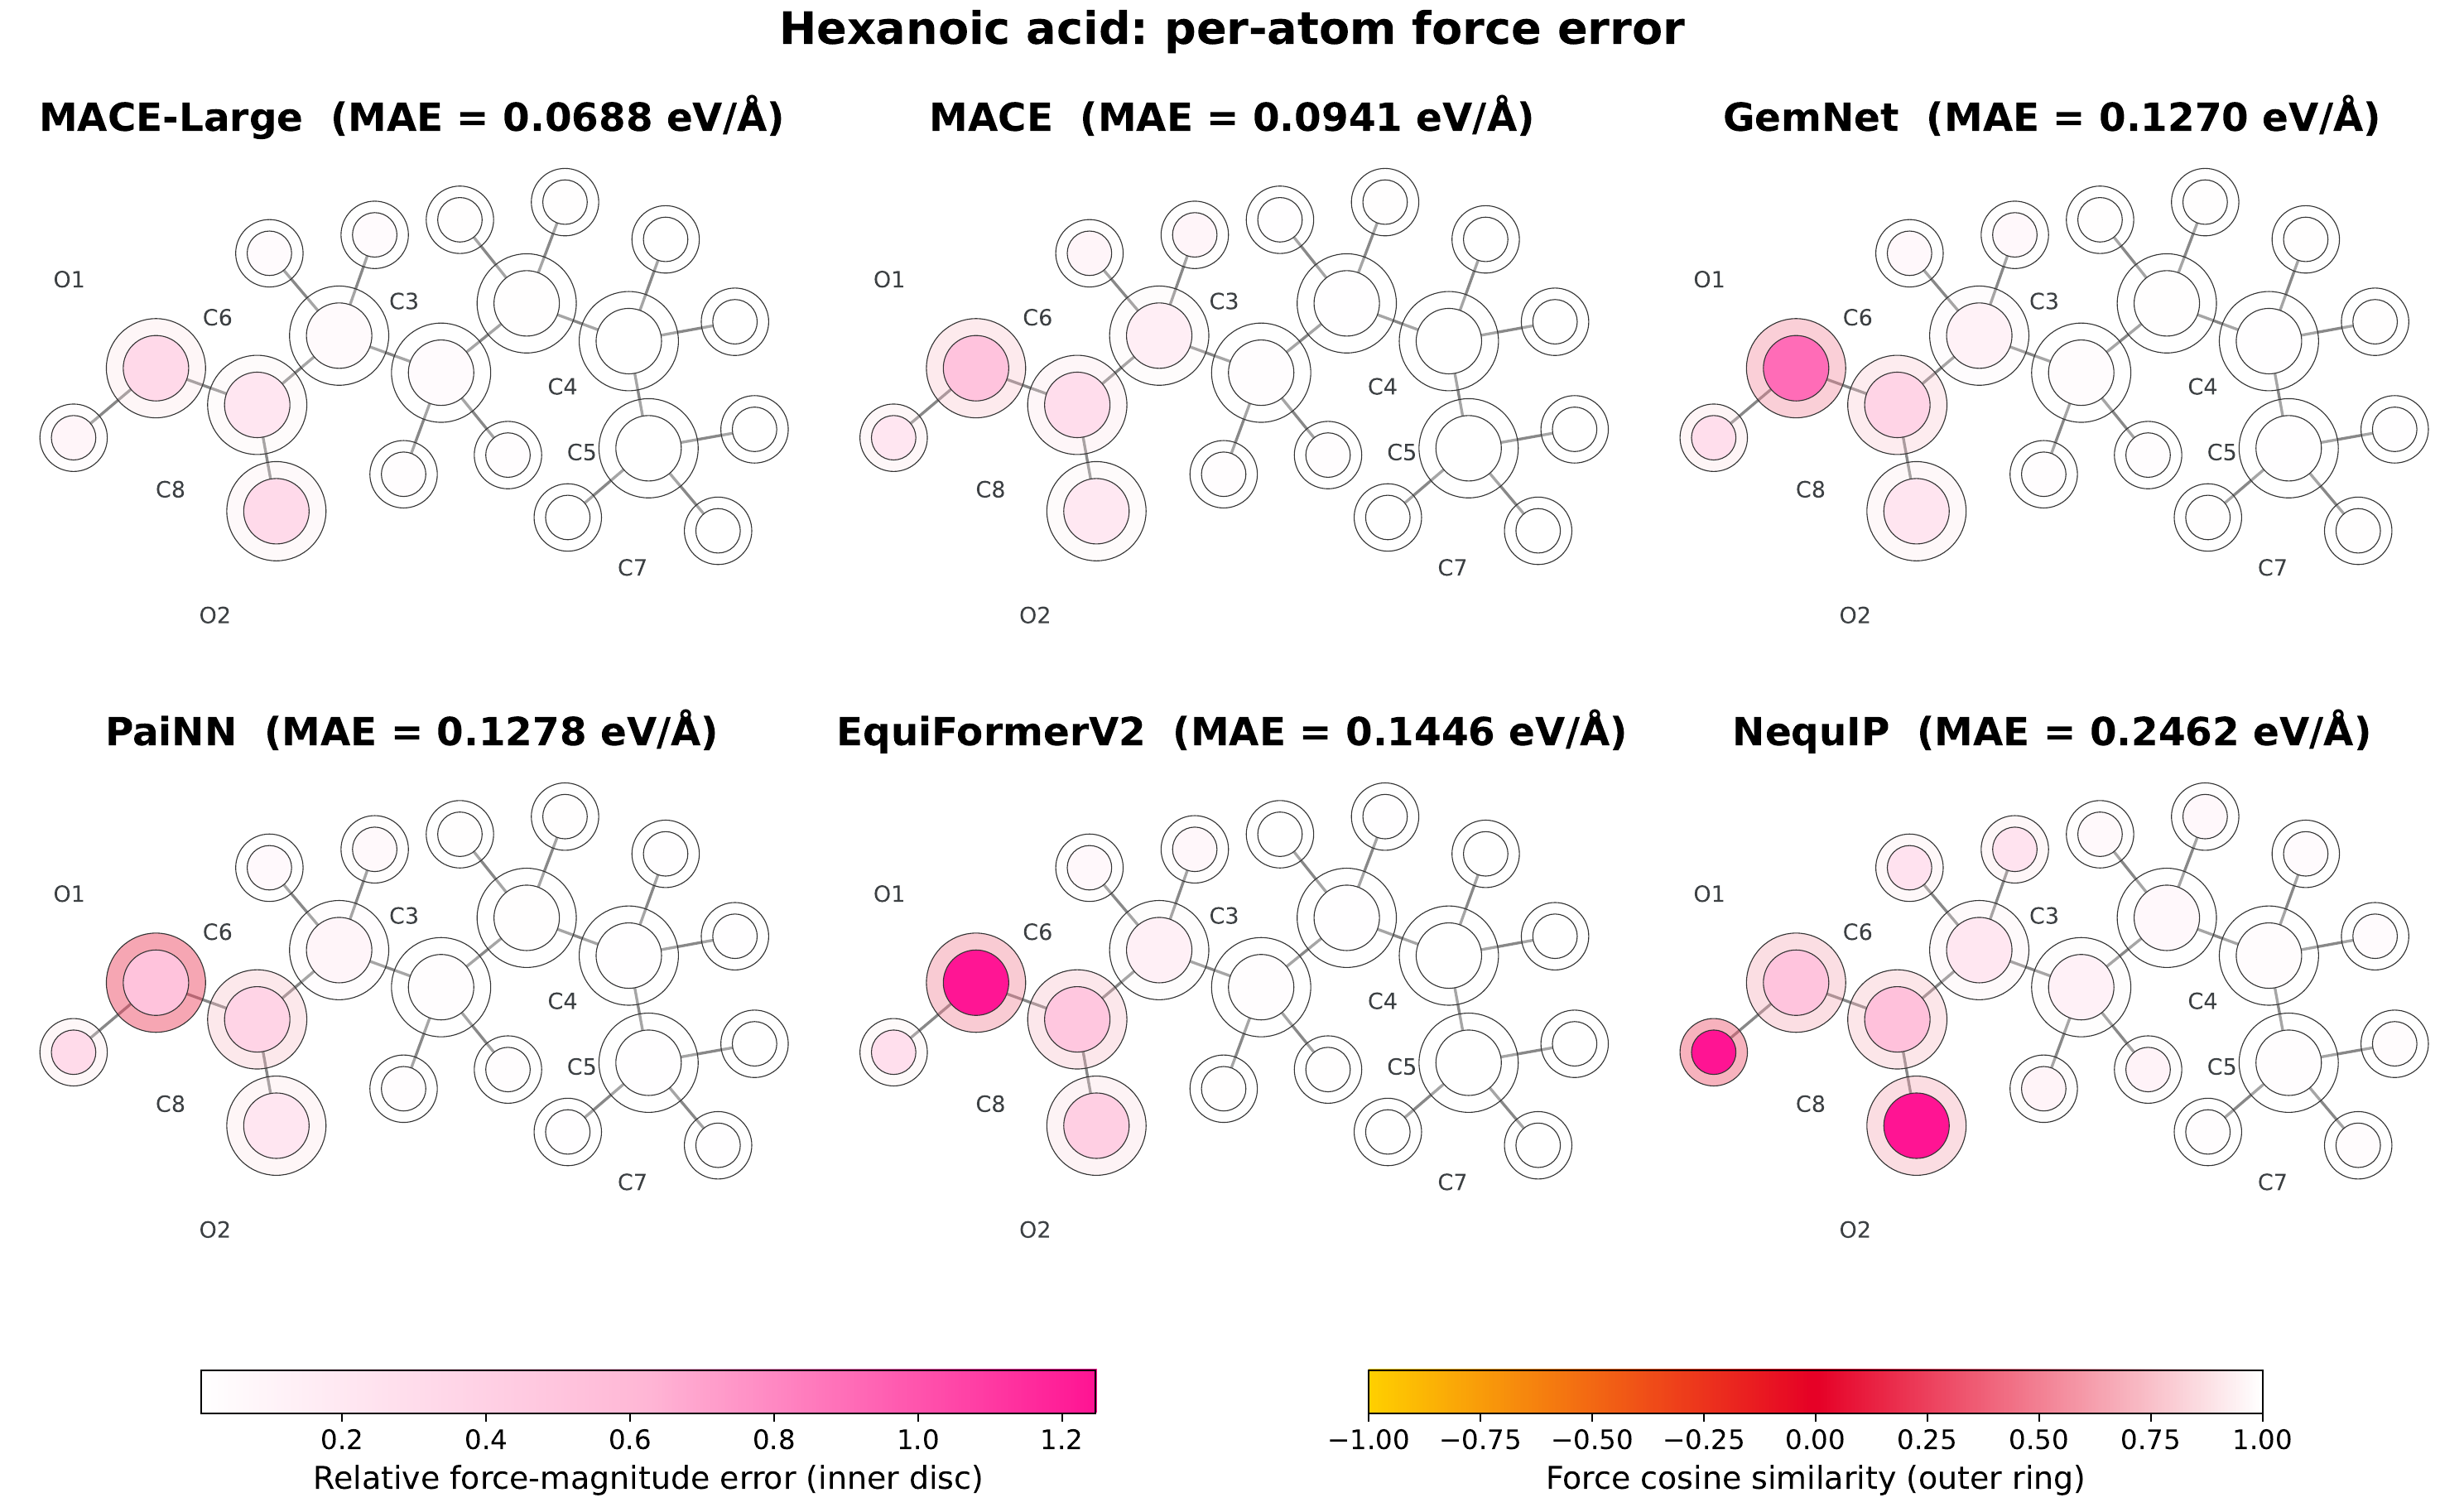
Where the failure happens: inside the molecule
- Hexanoic acid: new in the fusion task
- Inner disc: error in force strength; ring: error in direction
- Backbone fine; error on –COOH, mostly strength
–OH and C=O are known. –COOH is not.
Combining parts fails badly. How does the simplest task, a longer chain, compare?
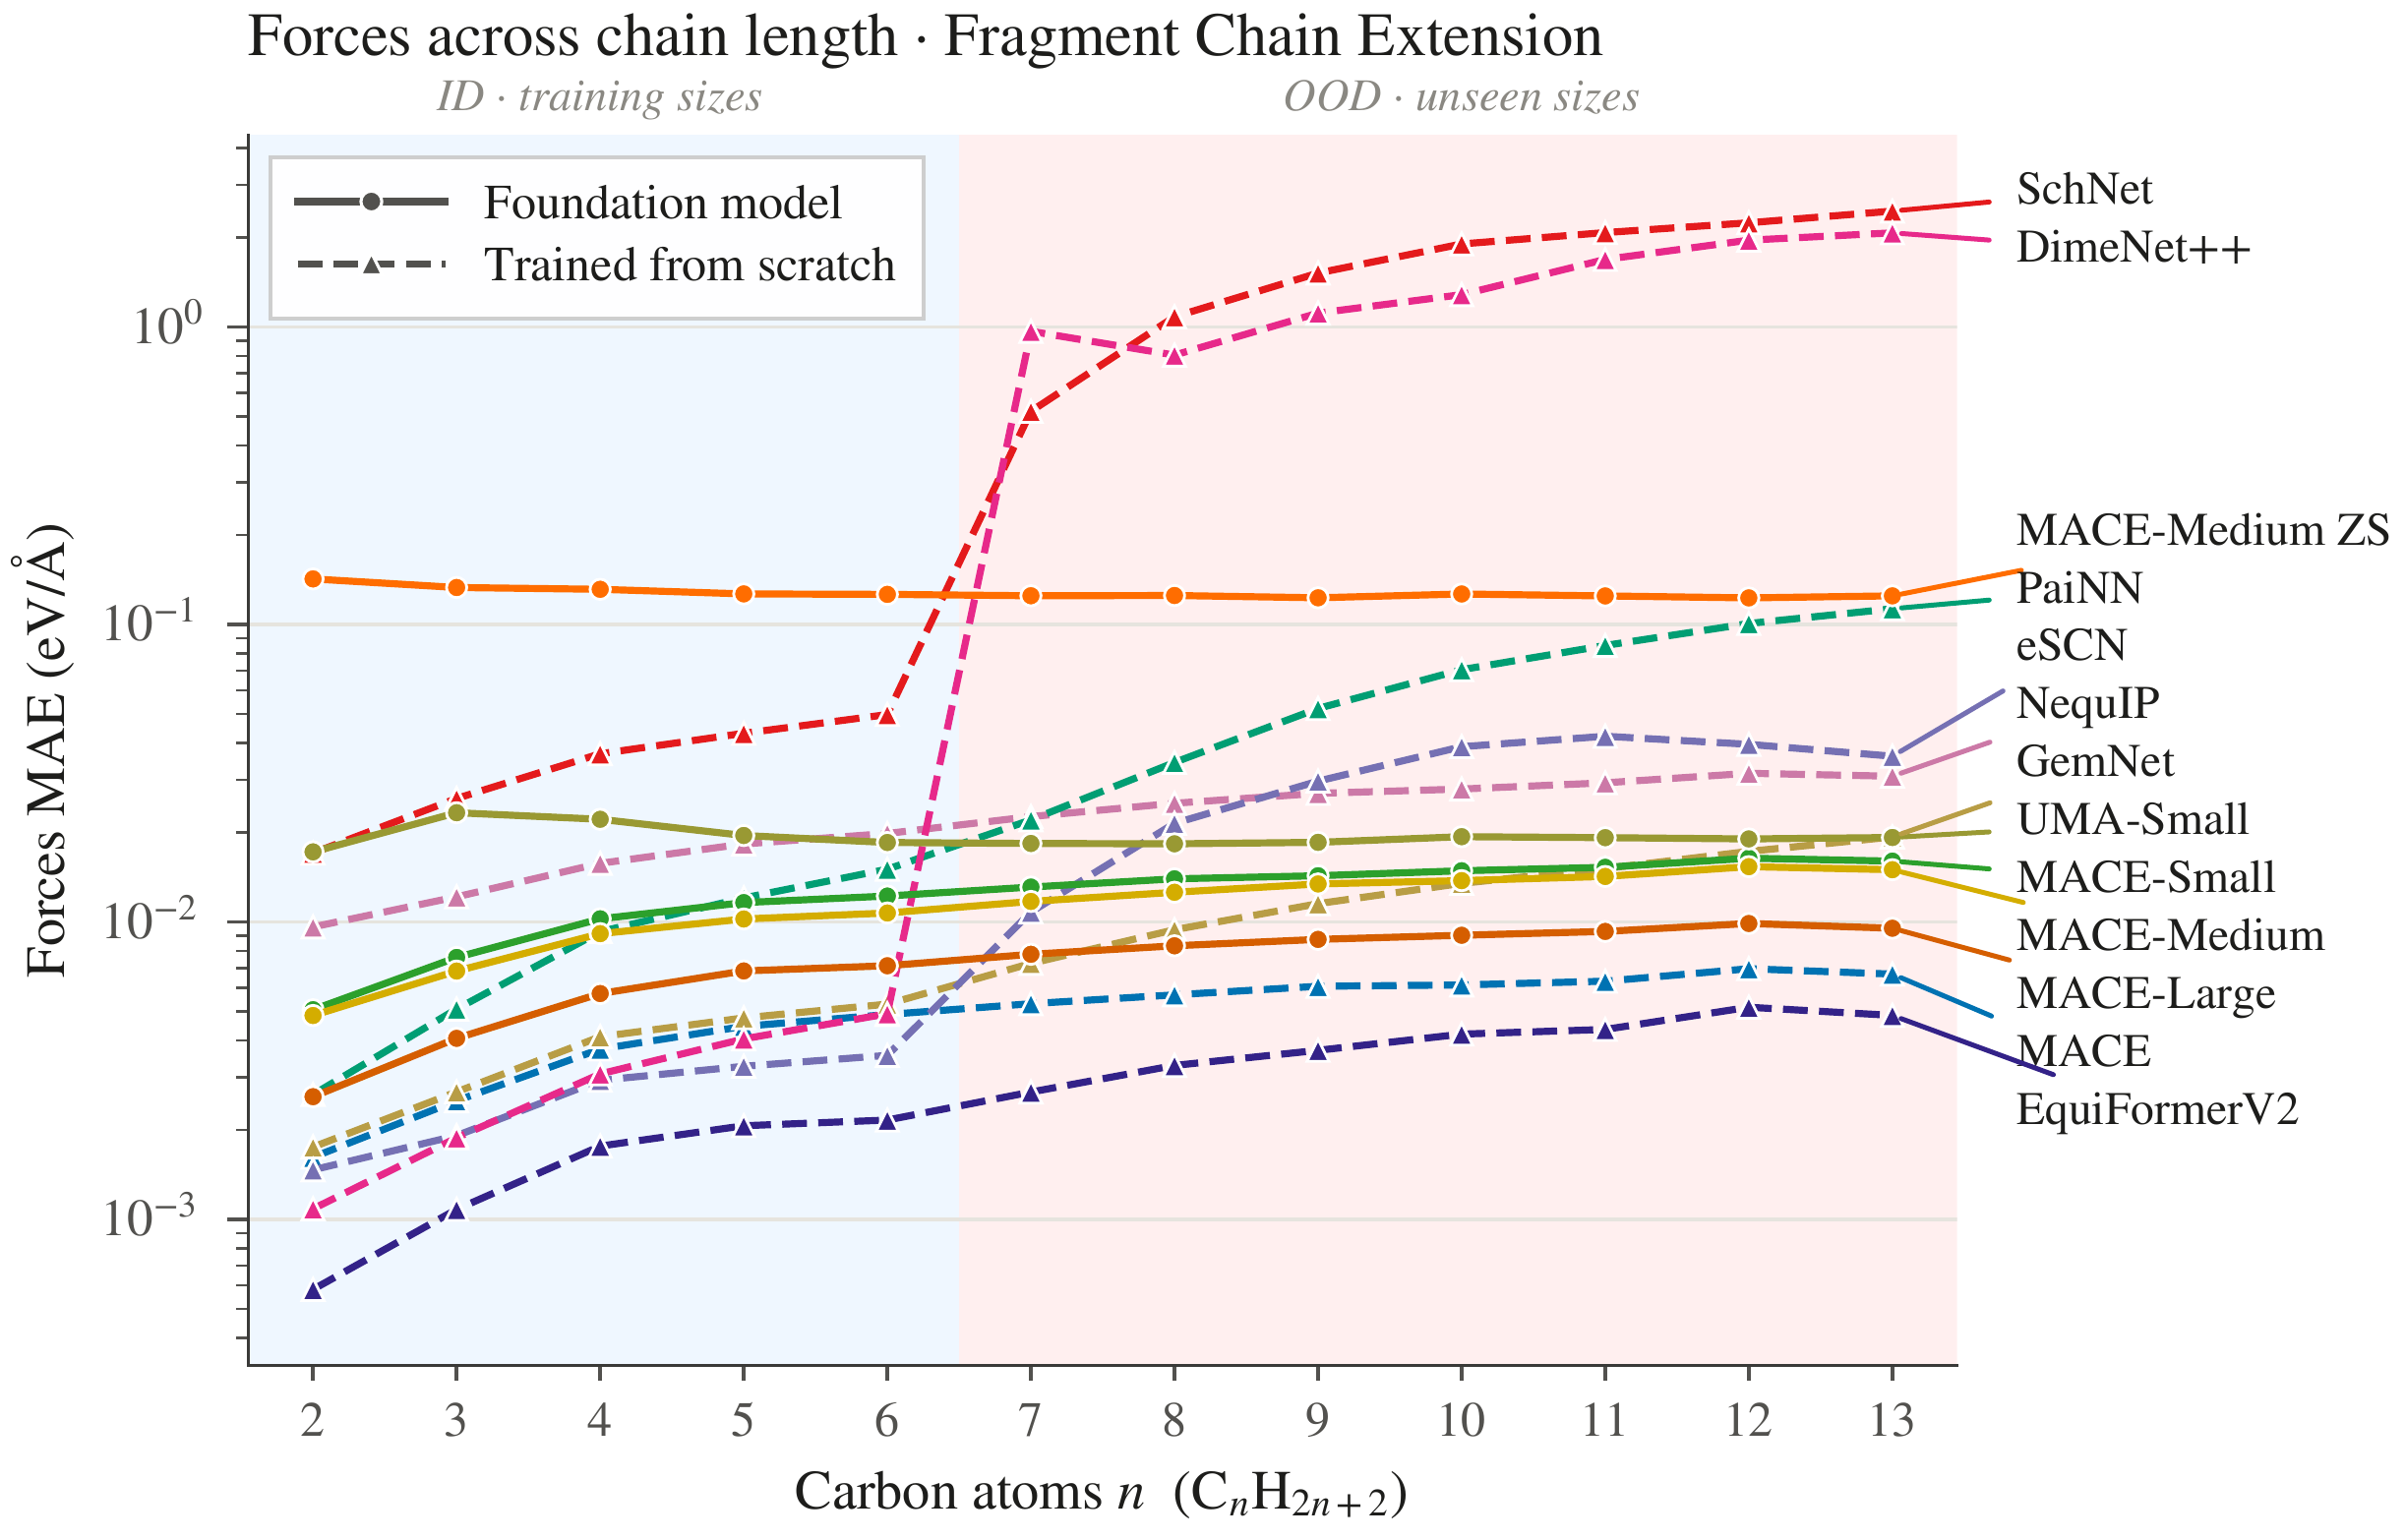
Chain extension: a smaller drop
- Train on ethane to hexane; test on heptane to tridecane
- Errors still rise on longer chains, but far less than in the other four tasks
- A longer chain adds more CH2, nothing chemically new
Repeating a known part costs some accuracy. Combining parts in a new way costs far more.
So what do we take home from all this?
Takeaways
- More of the same (longer chains) costs some accuracy; known parts in new combinations cost far more
- Wrong force strengths on a functional group mean wrong vibrations, wrong conformers, wrong barriers
- More data, bigger models and pre-training do not fix it
- Accuracy on known molecules does not predict accuracy on new ones
Before trusting a model on a new molecule, ask: has it seen this combination, or only these parts?
Thank you
Amir Masoud Nourollah
Stefano Leoni · Steven Schockaert
Paper: arXiv:2605.08988 (NeurIPS 2026)
Data: huggingface.co/datasets/AmirMasoud/GMD
Code: github.com/Nourollah/GMD-26
Questions?
Future work
What I am working on
- A model whose learning is guided by chemical structure
- It is forced to see a molecule the way a chemist does: as functional groups and how they connect
Goal: a model that understands a new molecule from its parts.
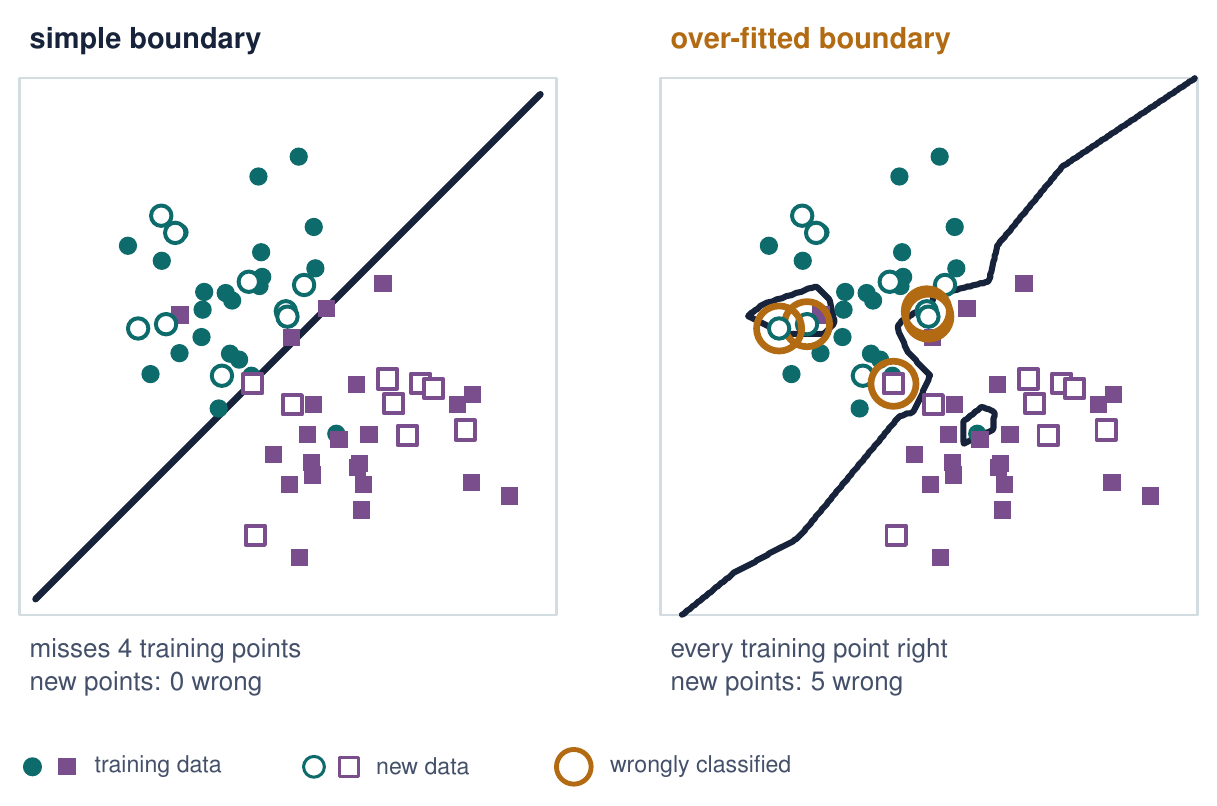
Fitting well is not generalising well
- Two kinds of points: the model learns a border between them
- A straight line misses a few training points, but gets new points right
- A wiggly border gets every training point right, and new points wrong
We want a model that works on data it has never seen, not one that remembers its training data. That is generalisation.
What about points that land outside everything the model has seen, or outside what our data covers?